An Azure gateway outage cut or degraded network connectivity for some Microsoft Azure customers in multiple regions from 20:30 UTC on September 30 until 02:15 UTC on October 1, 2026. Microsoft’s preliminary incident review (tracking ID 7Q30-010) lists five affected services:
- Azure ExpressRoute Gateway
- Azure VPN Gateway
- Azure Firewall
- Azure Application Gateway and Web Application Firewall
- Azure VMware Solution
ExpressRoute and VPN Gateway are the services companies use to link their own offices and data centers to Azure, so the incident landed on hybrid setups rather than on public websites. According to Microsoft, affected customers also saw gateways fail to load in the Azure Portal, and network management operations failed or ran late.
What Microsoft says went wrong
Two changes met. Microsoft writes that “a recent change to a regional gateway management service triggered a higher-than-expected load” while an unrelated operating system servicing maintenance “proceeded gradually through multiple regions.” The gateway management service would normally scale itself up. This time the extra work raised demand on the services it depends on, and those regional services could not scale as expected.
Microsoft paused the servicing maintenance as a precaution, then reverted the gateway manager change. That cut the load and let the affected services recover.
Timeline from the incident review
All times are UTC, as Microsoft gives them:
- 20:30, September 30: customer impact begins.
- 21:29: Microsoft starts investigating ExpressRoute Gateway connectivity problems in UK South.
- 22:27: the issue is found to affect multiple regions.
- 23:05: engineers link it to the operating system servicing work and pause that work.
- 01:36, October 1: most regions are recovering; configuration changes go to the rest, including France Central, North Europe, Southeast Asia, UK South and UK West.
- 02:15: Microsoft confirms the issue is mitigated.
That makes five hours and 45 minutes from first impact to mitigation. Microsoft notes that these times cover the whole incident and that actual impact varies between customers and resources.
What comes next
The review published so far is preliminary. Microsoft says it will finish an internal retrospective and publish a full Post Incident Review to impacted customers, “generally within 14 days,” and it is still investigating the scaling behavior and the safeguards needed to prevent a repeat.
The same status history page records a separate incident a day earlier: between 10:03 and 15:58 UTC on September 29, Azure OpenAI Service, Foundry and Cognitive Services requests in the Sweden Central region failed intermittently after a backend metadata service ran short of healthy instances.
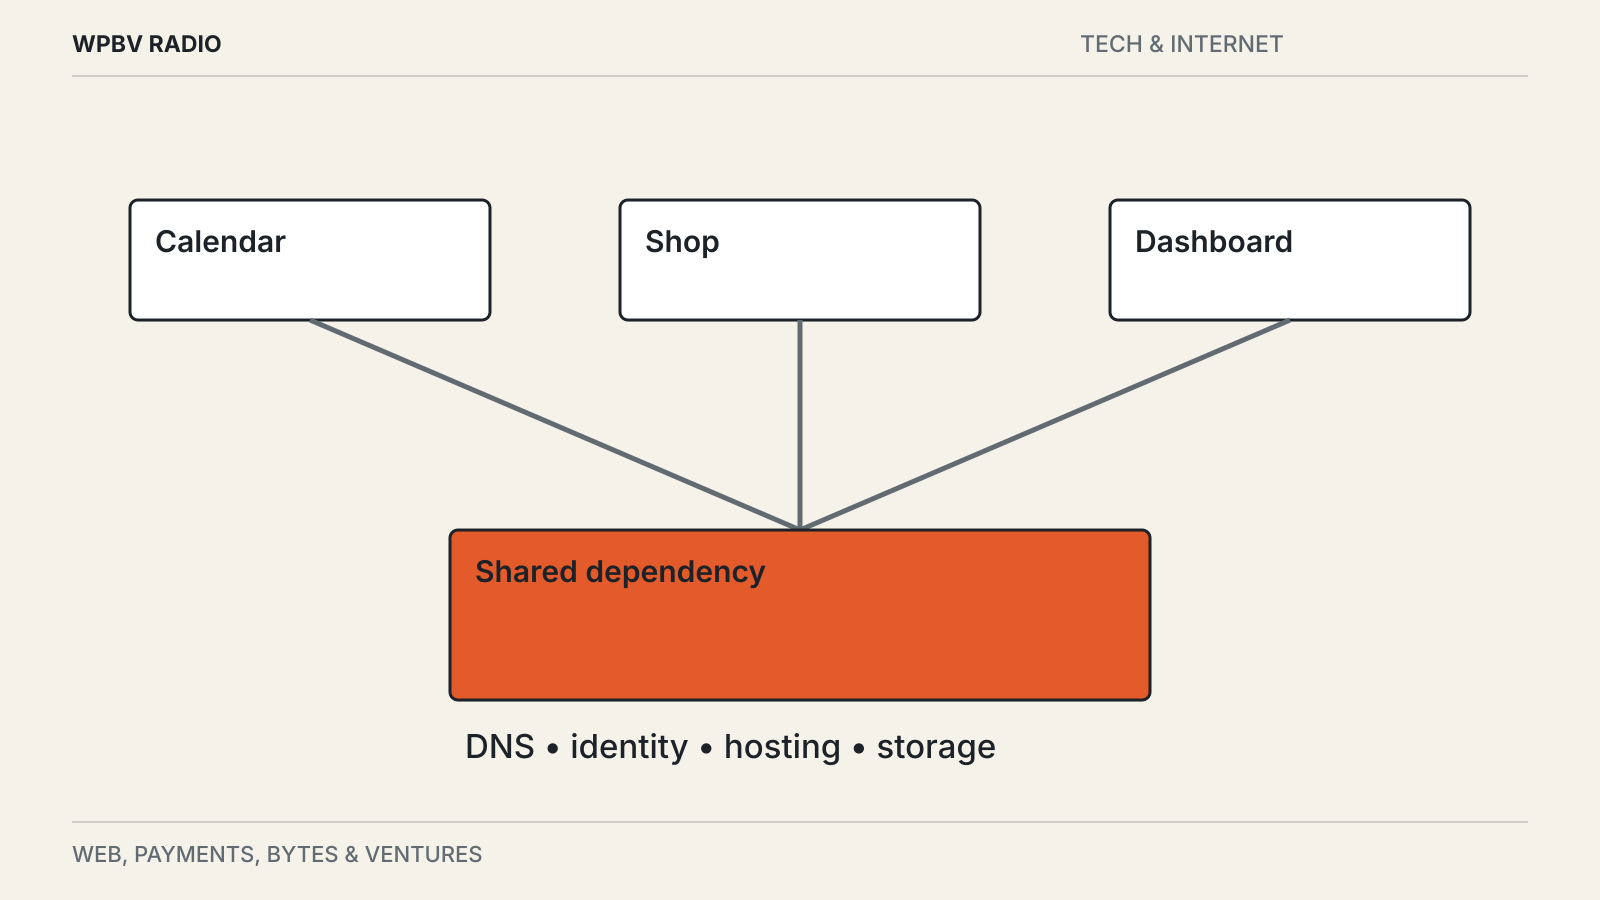
For teams that rely on a single ExpressRoute circuit or VPN tunnel, the September 30 incident is a reminder of the point we make in our explainer on why one cloud outage can break unrelated apps: the shared piece is often a management layer you never configured yourself. Microsoft’s own advice in the review is to set up Azure Service Health alerts so the full report reaches the right people. Earlier provider reports, with their causes and durations, are collected in our cloud outage tracker.